Why Avocado Datalake?
Supported products as of now
- Supports ingestion from RDBMS, NoSQL, and unstructured data sources
- Provides scalable ETL pipelines for data lake and warehouse synchronization
- Integrates with centralized data catalogs and access control systems
- Compatible with multiple cloud providers and open table formats
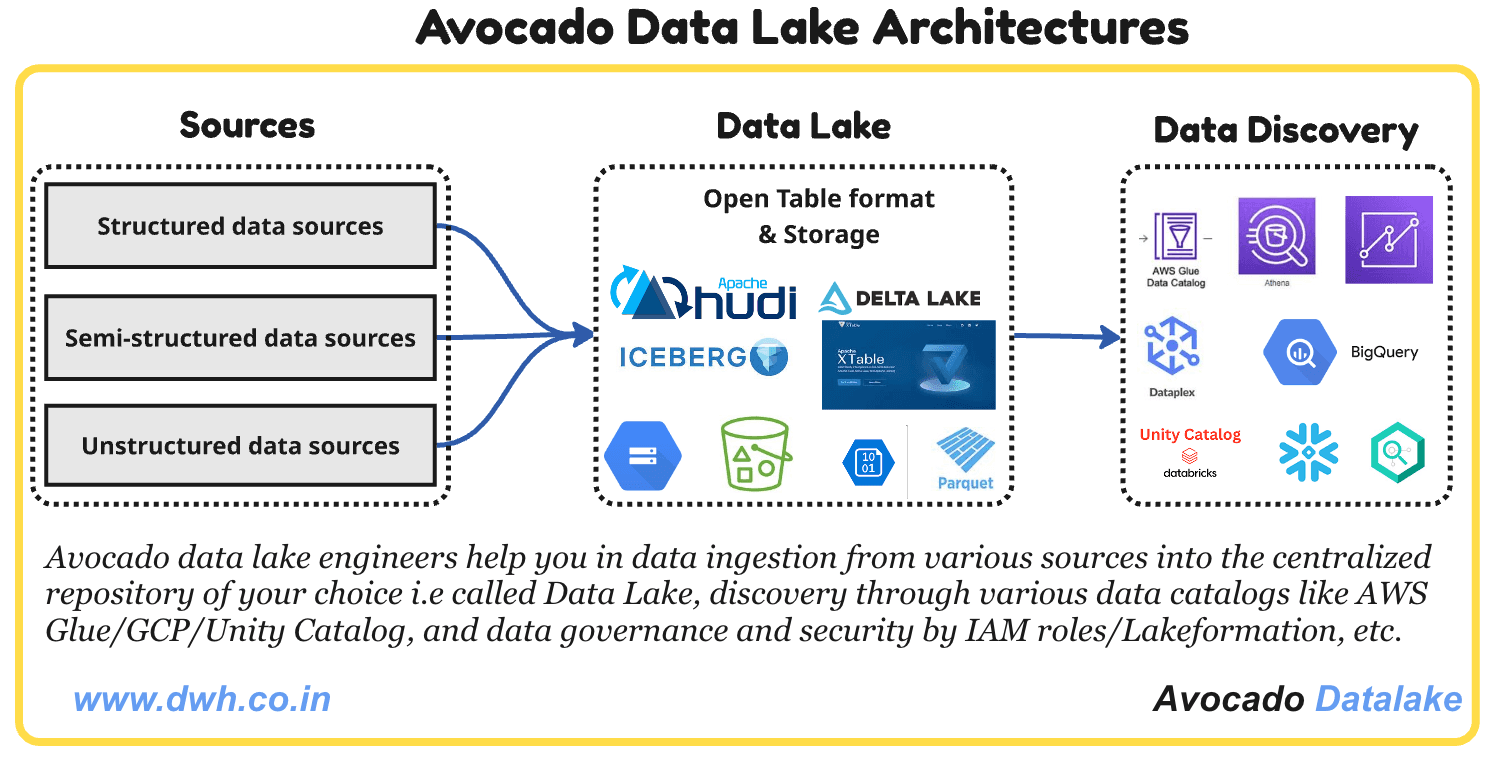
How it works
- Pipelines infrastructure is built using Terraform and can be deployed on AWS, GCP, and Azure.
- Pipeline ETL codebase is built using Apache Spark + Scala and fat Jar is created for each pipeline.
- We do support PySpark + Python in Databricks + Snowflake as well.
- Data catalog management using terraform and we do support Unity catalog in Databricks, AWS Glue Data Catalog, Azure Data Catalog, and Google Cloud Data Catalog.
- Permission on the datacatalog is managed by terraform as a code.
Need data lake or data warehouse solution implementation or bootstrapping in your organization?
Frequently Asked Questions
Why choose Avocado Datalake instead of building data pipelines from scratch?
Building data lake pipelines from scratch takes months of engineering effort, custom Spark boilerplate, and recurring maintenance. Avocado Datalake provides battle-tested, modular codebases with automated checkpointing, schema drift protection, and idempotency safeguards that deploy into your cloud account in days, not months.
Which open table formats and cloud platforms do you support?
We natively support Apache Iceberg, Delta Lake, and Apache Hudi across AWS (S3, Glue, EMR Serverless), GCP (GCS, Dataproc Serverless, BigLake), and Microsoft Azure (ADLS Gen2, Synapse), giving your business complete freedom from vendor lock-in and high-performance ACID transactions.
How does Avocado Datalake reduce cloud data engineering costs?
Our pipelines run on serverless, pay-as-you-use Spark compute rather than persistent, idle VM clusters. Crucially, maintaining a single authoritative copy of data in open table formats allows multi-engine querying across BigQuery, Snowflake, and Databricks without duplicate data ingestion or storage fees.
How is data catalog governance and access control managed?
We integrate with centralized catalogs like Databricks Unity Catalog, AWS Glue Data Catalog, and GCP Dataplex. All permissions, column/row-level access control policies, and infrastructure resources are managed declaratively as code via Terraform.