Avocado Datalake Products
We are specialized Data Engineering Services provider of Data Engineering Products for Data Lake and Data Warehouse.
We provide the following ingestion solutions for your organization sooner than any other consultancy company. We already have the highly scalable and configurable codebase ready for you to use and get started with your own data lake in your organization based on your chosen cloud provider weather it is AWS, GCP or Azure. We have the following offering available and only need to configure in your cloud provider:
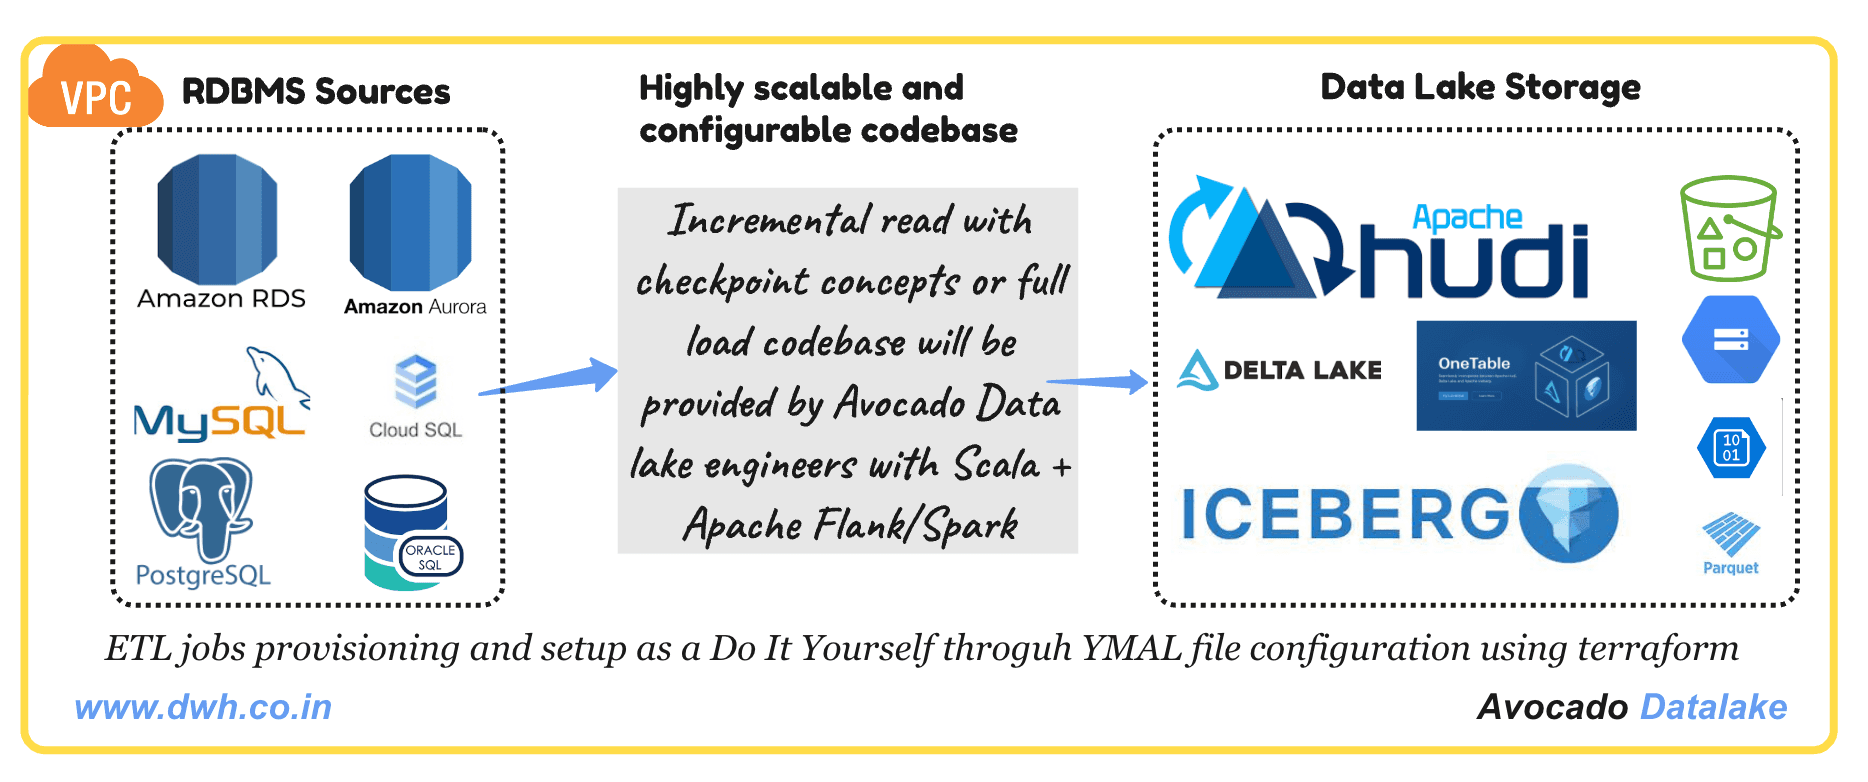
Structured Data Sources (RDBMS databases) to Data Lake
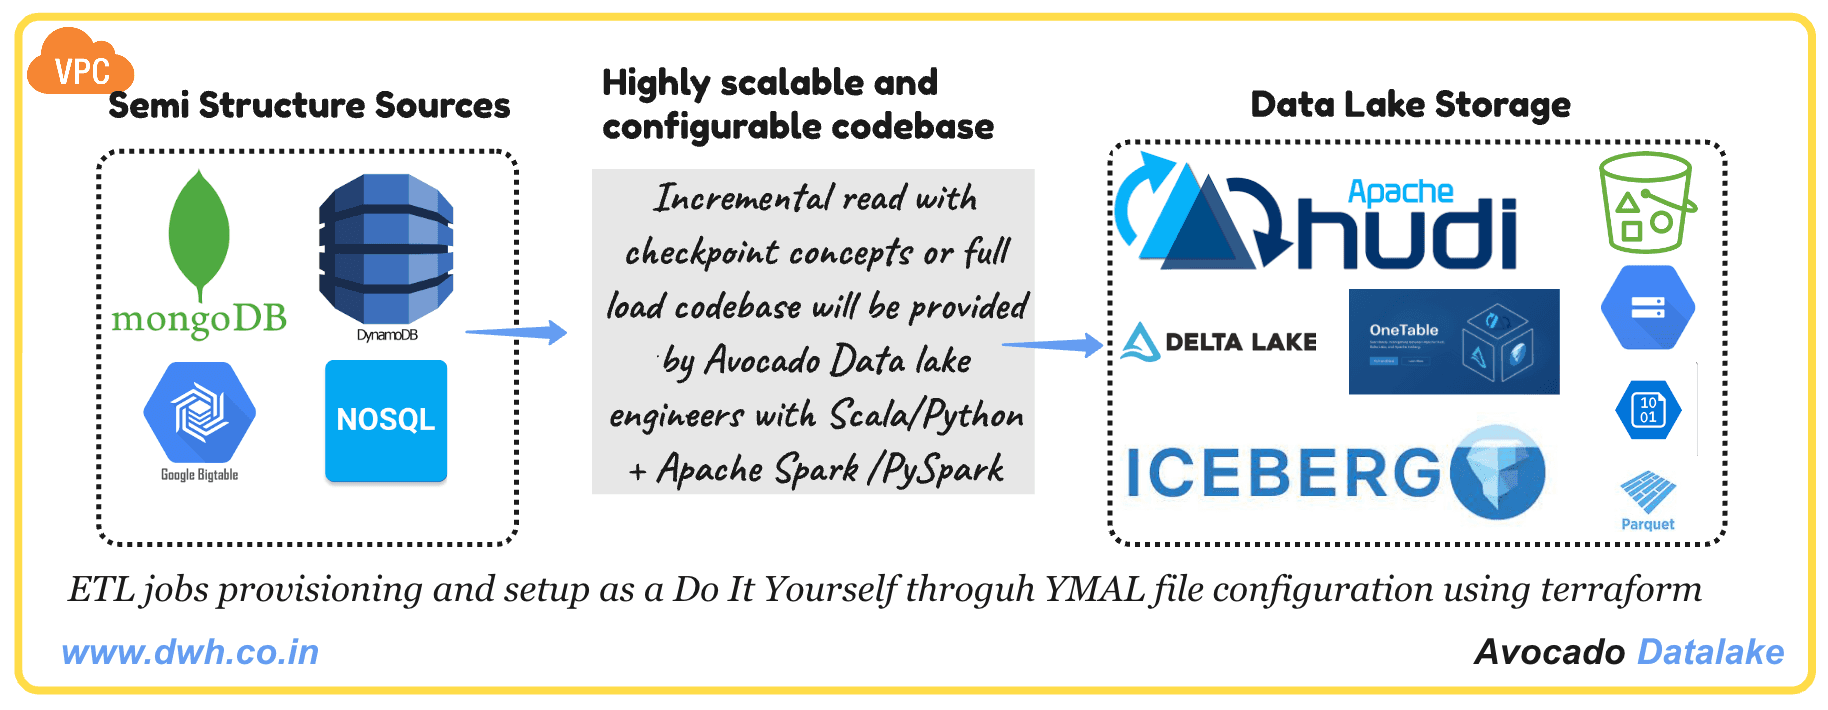
Our high level ingestion design of RDMBS data sources to data lake:See a detailed implementation of custom ETL pipeline on GCP cloud using Dataproc Serverless and Apache Iceberg format.Semi-Structured Data Sources (NoSQL databases) to Data Lake
Our Semi Structured Data Sources extraction classes are designed with the concept of Factory Design Pattern to extract sources based on the configuration parameters, source data and return it as a data frame, and then pass to transformation layers or Load layers where it will be written to centralized data lake based on the configuration of table format and your choicen cloud.Unstructured Data Sources (CSV, JSON, Text documents) to Data Lake
Leverage unstructured data into your centralized data lake for advanced analytics and machine learning using our highly configurable ETL pipeline.See a detailed implementation of custom pipeline for GCS files to Iceberg Lakehouse on GCP cloud using Dataproc Serverless.Data Lake to Data Warehouse (AWS Redshift, GCP BigQuery, Snowflake)
Data Lake/Other sources to Data Warehouse (AWS Redshift, GCP BigQuery, Snowflake)


For the each offering, visit the respective offering page and checkout the implementation details and the timeline needed to be implemented in your organization as per your chosen cloud provider.
About our ingestion solution into Data Lake
Once the data available in the data lake with open table format as below:
- Apache Iceberg
- Apache Hudi
- Delta Lake
- Apache XTable

We attach DataLake with centralized data catalog for discovery and utilization using the below tools as per your organization needs.
- AWS Glue Data Catalog
- GCP Data Catalog
- Apache Atlas
- Databricks Unity Catalog
After the data is available through any of the above centralized catalog, we will help you build the access controls using the IAM or Lakeformation in the AWS Glue data catalog. Access controls can be provisioned through our specialized Terraform module, as per your need to provide access to various groups in your organization, or you can configure the access yourself. Examples of intended access control users are:
- AI/ML Engineers
- LLM Engineers
- Data Engineers
- Data Scientists
- Data Analysts
- Business Intelligence
Our High level architecture design of the above centralized data lake for utilization by the end users from various tools is as follows:

For more information on Avocado Datalake codebase or if you want to get bootrapping in your organization or full access and support for any of the above proposed soltutions then email us at We will shortly contact you and setup a call a free half an hour call.
Frequently Asked Questions
How quickly can these data pipeline products be deployed?
Our modular ETL/ELT codebases are designed to be configured and deployed into your AWS, GCP, or Azure cloud account within days using automated Terraform modules and CI/CD pipelines.
What open table formats do your pipeline products support?
All products natively support Apache Iceberg, Delta Lake, and Apache Hudi, ensuring ACID transactions, time travel, and complete independence from proprietary formats.
Are these pipelines serverless or do they require dedicated infrastructure?
Our pipelines are designed for ephemeral, serverless Spark compute (like GCP Dataproc Serverless or AWS EMR Serverless), running strictly pay-as-you-use without paying for idle cluster uptime.
How do you handle schema evolution and incremental ingestion?
Our pipelines incorporate automatic schema inference, drift handling, and bookmark/checkpoint-driven incremental processing so only newly landed or mutated records are scanned.